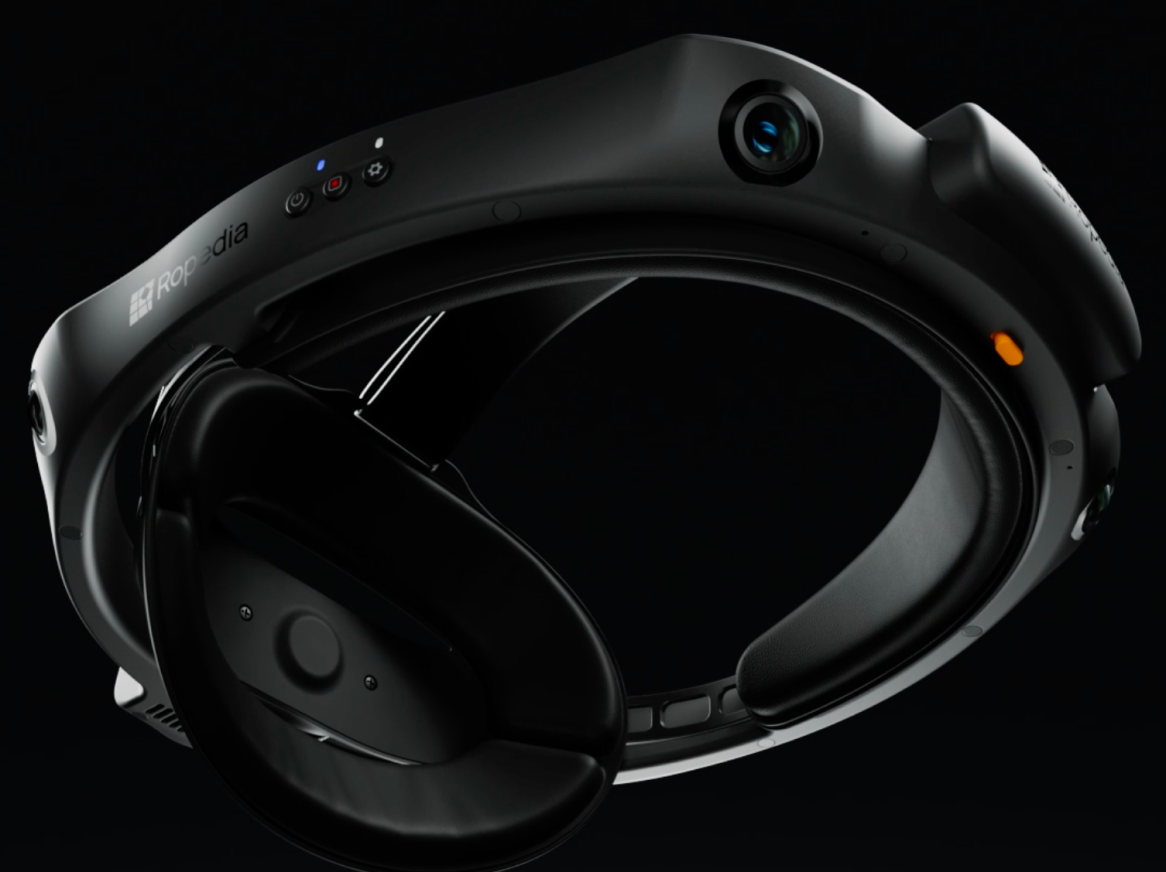

0°
Coverage
Introduction
Physical AI is missing the raw material for its next scaling curve: human xperience™.
Ropedia is building the infrastructure to capture, structure, and scale that experience — turning how humans see, move, and interact with the physical world into training-ready intelligence.
With HOMIE Gen2, we unlock the Experience Scaling Law for Physical AI.
Key stats
0°
Coverage
0 Channel
Spatial audio
0 FPS
Global shutter
0P
Video quality
Up to 0TB
Storage
0g
Light weight
| Parameter | Value | Parameter | Value |
|---|---|---|---|
| Dimensions | 300×240×138 mm | Weight | 380 g |
| Cameras | 4 | Video Resolution | 1080P @ 30fps |
| Video Format | MP4 | Camera FOV | Horizontal 162°, Vertical 109° |
| IMU | 200 fps | Bluetooth | Bluetooth 5.2 (BR/EDR & BLE) |
| Built-in Mics | 4 Digital MEMS Microphones | Storage | microSD Card (up to 2 TB) |
| Buzzer | Prompt Sound for Different Scenarios | External Ports | USB Type-C ×1 (Data), USB Type-C ×1 (Full Function), PPS Port ×2 |
| Power Input | 5V DC Input | Battery | 3.6V 3000mAh Lithium Battery (Built-in) |
| Battery Life | Up to 90 min recording / ~4 hrs standby | Wi-Fi | Wi-Fi 5 (IEEE 802.11 a/b/g/n/ac), 2.4 GHz & 5 GHz |
Chapter 01 · Foundations
Why physical AI needs 4D data.
We use Xperience deliberately. The X stands for the many dimensions of human experience — what humans see, hear, touch, move, and interact with as they live and act in the real world.
Human Xperience is not just perception. It is perception tightly coupled with action, intention, and physical consequence — what we call 4D data: spatial structure, motion, interaction, and change over time.
To capture it faithfully, we must start from the perspective where experience originates.
If we want AI systems that understand and operate in the physical world, we must teach them from the viewpoint that best reflects real human behavior: the egocentric perspective.
From the egocentric perspective, human experience naturally includes:
This is exactly the information an intelligent embodied AI system needs to learn how to move, manipulate, and reason about the physical world.
Why egocentric scales
Egocentric capture scales. A body-mounted system, without external infrastructure or environmental instrumentation, enables truly in-the-wild data collection across homes, workplaces, factories, hospitals, and beyond.
This scalability unlocks the diversity, realism, and long-tail behaviors that are critical for robust generalization in robotics and embodied AI.
Chapter 02 · The Platform
A full-stack platform for in-the-wild human experience capture.
To make large-scale human Xperience capture possible, we built HOMIE (Human-centric OMni Interaction & Experience) — a full-stack hardware-software platform designed for frictionless, lossless human-centric data capture at scale and low cost.
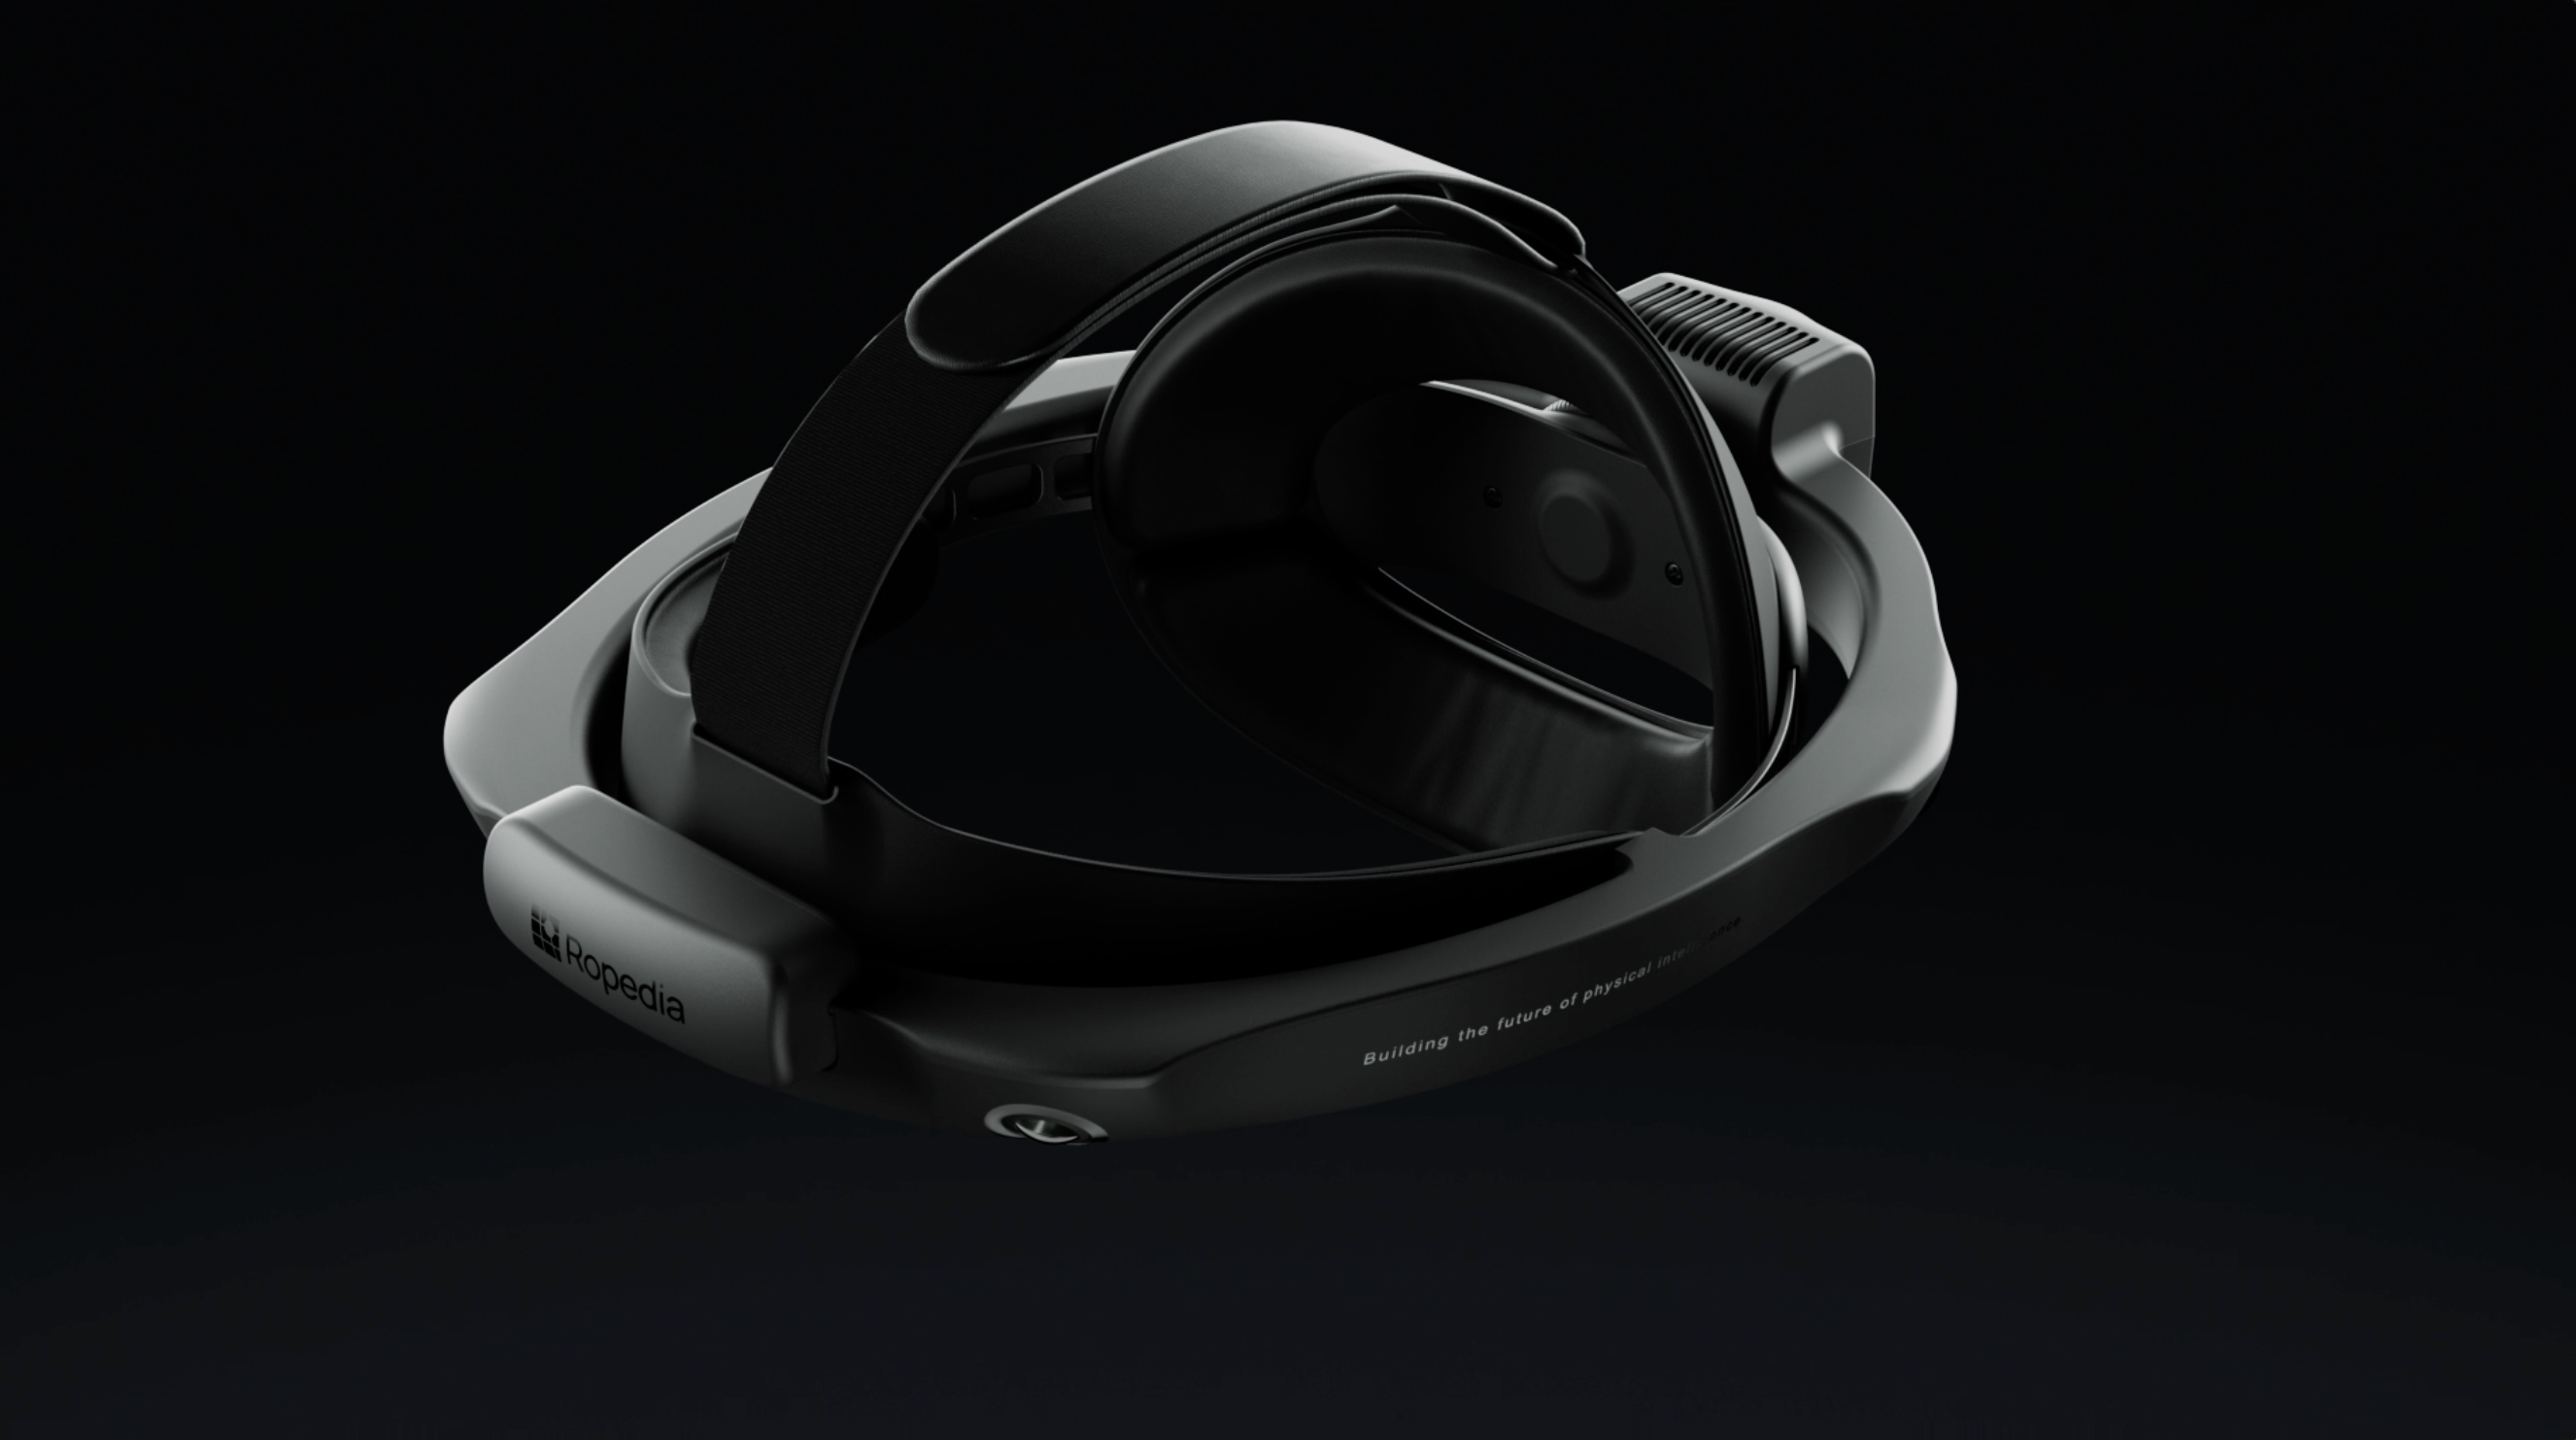
HOMIE's hardware is engineered for accurate spatial understanding and long-term real-world use:
Our goal is simple: make capturing human Xperience as natural as wearing glasses.
Most robotic datasets observe people from the outside. HOMIE captures from within the experience. Four wide-angle cameras provide 162° of coverage each, creating a full 360° view around the wearer.
This means the dataset captures not only what the person is looking at, but also what is happening around them — including objects, spatial relationships, movement, and environmental changes outside the immediate field of view.
Because physical tasks rarely happen in a single direction, 360° coverage preserves the context that conventional forward-facing capture misses.
What humans see. What humans do. Where humans are. What the world does in response.
All captured as one continuous and immersive experience.
Raw experience alone is not enough. Intelligence requires structure.
HOMIE includes a suite of proprietary spatial foundation models that automatically transform captured Xperience into machine-readable, model-ready annotation, including:
Together, these models convert unstructured human experience into structured interactive intelligence datasets — ready for training the next generation of robotics models, world models, and embodied AI systems.
Physical intelligence cannot be learned from a single sensor.
HOMIE Gen2 synchronizes multimodal signals into a common temporal and spatial representation, allowing models to understand human behavior as a complete sequence rather than a collection of disconnected streams.
The Xperience data engine can include 10+ different modalities:
Chapter 03 · RE-LIVING THE DATA
How embodied AI learns from human Xperience.
Intelligence does not emerge from passive observation alone. It emerges through ReXperience: the process by which AI systems repeatedly relive, model, and internalize human Xperience.
We see immediate impact of ReXperience across three frontier directions in physical AI:
World models - predictive intelligence from human Xperience
Egocentric human Xperience provides realistic trajectories for learning how environments evolve and how actions lead to consequences. This grounds world models in real perception and interaction, improving physical prediction and reasoning. At scale, it enables world models that generalize across diverse, unstructured real-world scenarios.
Real2Sim - better robot training simulations from human-captured reality
Simulation remains essential for robot learning, but its fidelity is fundamentally limited by the realism of its assets. Human Xperience supplies natural motion patterns, contact dynamics, and task distributions that simulations often miss. By grounding simulation in real human behavior, Real2Sim produces training environments that are more representative, diverse, and effective for robotics.
VLA models - scaling generalization through egocentric action grounding
Large-scale egocentric Xperience exposes Vision-Language-Action (VLA) models to how humans actually perceive, act, and describe tasks in real environments. This grounding leads to much stronger generalization across new tasks, instructions, and scenes. As Xperience scales, so does the model's ability to adapt and act intelligently in the open world.
Chapter 04 · Closing
Defining the data foundation for physical intelligence.
If we want AI that moves like us, understands like us, and helps us in everyday physical tasks, then its intelligence must be built from human experience itself. At Ropedia, we are building the data infrastructure that captures, structures, and transforms human Xperience into the foundation for physical intelligence.
Closing thought
Intelligence begins with Xperience. We're here to scale it.
// TALK TO US
If you are building world models, robotics systems, or embodied agents and care deeply about learning from real-world human experience data we'd love to talk.
Contact Us


